FLUX.3 [klein] API
Black Forest Labs' small, open, fast image model
A 5.6B open-weights model that generates, edits and composes from ten references at up to 4K, runs on an 8 GB GPU, and returns a 1 MP image in about four and a half seconds.
- Kind: image
- Made by: Black Forest Labs
- Price: 1.6 credits per image 1K, 2.5 2K, 6.5 4K (from $0.016; 1 credit = $0.01 on monthly plans, $0.015 as a top-up)
- Released: 2026-10-15
- Open weights: yes (Open weights, FLUX Kommunity License v1.0 (commercial use allowed under USD 5M annual revenue))
- Parameters: 5.6B image transformer
- Text encoder: Qwen3-VL-4B-Instruct
- Max resolution: 4K (1K, 2K, 4K on Unicorn)
- Reference images: Up to 10 per edit
- Tasks: Text-to-image, editing, multi-reference
- Local hardware: 8 GB VRAM with the INT8 build
- Licence: FLUX Kommunity License v1.0
- Inputs: seed, width, height, prompt, num_images, resolution, aspect_ratio, nsfw_checker, output_format, enhance_prompt
Call it with POST https://api.unicornapi.net/v1/jobs and model flux-3-klein-text-to-image, or try it in the Playground.
Where it shines
- +91 Elo text-to-image and +70 Elo editing over FLUX.2 [klein] 9B in BFL's tests, with 38% fewer parameters
- Native 4K output and up to ten reference images in one model
- Open weights that run on consumer GPUs from 8 GB
- Accurate lettering on posters in early independent tests
- Median API latency of about 4.5 seconds per 1 MP image, by BFL's figures
Watch out for
- Early users report weak anatomy and faces in people shots
- Small text, diagrams, counting and spatial relations are unreliable
- Trained on long captions: short prompts give generic results without prompt enhancement
- Commercial self-hosting needs a separate licence above USD 5M annual revenue
Made with Flux 3 Klein Text to Image
FLUX.3 [klein] is the small, open member of Black Forest Labs' third FLUX generation. It is a 5.6-billion-parameter image model that generates pictures from text, edits existing images on instruction, and composes new scenes from up to ten reference images, all in one set of weights. Black Forest Labs published the weights on 15 October 2026, two weeks after its API-only flagship, FLUX 3 Image, and describes Klein as carrying over that model's headline features: native 4K output, bounding-box layout control and edits that leave the untouched parts of a picture alone.
The interesting part is the ratio of size to ambition. Klein is smaller than the 9B model it replaces, yet Black Forest Labs reports that it beats it by a wide margin in its own preference comparisons, and that it ranks first against larger open models such as Qwen-Image 2.1 and Krea 2. With an INT8 build it runs on GeForce RTX cards with as little as 8 GB of video memory, and the step-distilled version produces a one-megapixel image in about four seconds on an RTX 5090.
It is also quick to call through an API, which is how most people will meet it. That speed, together with the editing endpoint and its ten-image references, makes Klein a natural pick for high-volume work: catalogue variations, quick layout drafts, and batch edits where a flagship model would be overkill.
Black Forest Labs and the road from FLUX.2 [klein]
Black Forest Labs is the Freiburg-based lab founded by researchers behind the original latent diffusion work, and the FLUX name has covered its models since FLUX.1. The lab has always run two tracks side by side: closed "pro" models sold through its API, and open-weight models that developers can download, fine-tune and run locally.
The "klein" (German for small) line is the open, compact track. FLUX.2 [klein] arrived in January 2026 in two sizes. The 4B model shipped under Apache 2.0, while the 9B model, the stronger of the two, carried a non-commercial licence. Both were built for speed and unified text-to-image, editing and multi-reference generation in a single model.
FLUX.3 [klein] replaces that pair with one 5.6B model, released alongside a base checkpoint for fine-tuning, a step-distilled checkpoint for fast generation, and FP8, INT8 and NVFP4 builds. The weights sit in gated repositories on Hugging Face, with reference inference code on GitHub and day-one support in ComfyUI and Hugging Face Diffusers. Black Forest Labs says the model was trained on NVIDIA GB200 NVL72 systems.
The licence is new too. Klein uses the FLUX Kommunity License v1.0, which allows non-commercial use plus commercial use for individuals and companies whose gross annual revenue, affiliates included, is below USD 5 million. Larger organisations need a separate agreement to self-host the weights commercially, or can use a hosted API. The licence also forbids using the model or its outputs to improve a competing model. For a small studio that is more freedom than the FLUX.2 [klein] 9B licence gave; for anyone who relied on the Apache 2.0 terms of the 4B model, it is less.
What changed from FLUX.2 [klein]
Black Forest Labs frames the upgrade with three numbers from its internal evaluations: compared with FLUX.2 [klein] 9B, the new model gains 91 Elo in text-to-image and 70 Elo in image editing while using 38% fewer parameters. In the same charts it ranks first in text-to-image, multi-reference generation and editing against Qwen-Image 2.1 (7B), Krea 2 (12.9B) and its own predecessor, and it is shown ahead of two closed models, Ideogram V4.5 and FLUX.2 [pro].
Beyond the scores, the concrete changes are these:
- Native 4K. FLUX.2 [klein] topped out at about four megapixels. Klein renders up to 4K, the same ceiling Black Forest Labs offers on its flagship.
- Bounding boxes. Prompts can carry boxes that say where each described element should land in the frame. The model card is careful to say that boxes set placement and scale but are not a hard mask. On Unicorn API the two endpoints take a plain prompt and have no separate box field.
- Ten references. Multi-reference composition now takes up to ten input images, for jobs like placing several products into one scene or keeping a character consistent.
- A vision-language text encoder. Klein reads prompts through Qwen3-VL-4B-Instruct instead of the Qwen3 text encoder used by its predecessor, and keeps the FLUX.2 autoencoder.
- A dedicated prompt upsampler. Black Forest Labs ships a 9B vision-language model, fine-tuned from Qwen3.5-9B, that rewrites short requests into the long scene captions Klein was trained on.
- Pixel restoration on the API. The hosted distilled model adds a step that keeps unedited regions of an image exactly as they were, which matters most for repeated edits.
One caution belongs here: Black Forest Labs has not published how its Elo comparisons were run, how many raters took part, or the prompt sets. The charts also leave out the strongest closed models of the moment and the lab's own FLUX 3 Image, so they show where Klein sits among open models more than where it sits overall.
How it works: a small transformer with a large helper
Black Forest Labs has published the components rather than a technical report. The image generator is a 5.6B diffusion transformer. Prompts are encoded by Qwen3-VL-4B, a vision-language model released under Apache 2.0, and images are decoded with the FLUX.2 autoencoder. The base checkpoint runs 50 sampling steps with classifier-free guidance; the distilled checkpoint needs 16 steps and no guidance, which is where most of the speed comes from. LoRAs trained on the base model can be applied to the distilled one, and BFL suggests a scale of 0.75 when doing so.
The upsampler deserves more attention than it usually gets. Both the model card and the GitHub repository say, in so many words, not to use Klein without it, because the model was trained on the captions the upsampler writes. A short prompt such as "a man walking with his dog" goes in; a paragraph comes out describing medium, style, framing, lighting, camera and each subject's colour, material and position. Without that step, the model card warns, short prompts produce generic output.
That design explains the hardware picture. The generator weights take 11.2 GB in BF16 and 5.6 GB in FP8, and the INT8 build fits 8 GB cards. The upsampler adds roughly 28 GB on top, so most local users either point Klein at a hosted language model for the rewrite or use an API that does it for them. On Unicorn API the enhance_prompt option, on by default, performs this rewrite before generation.
Specs at a glance
| FLUX.3 [klein] | |
|---|---|
| Parameters | 5.6B image transformer (text encoder separate) |
| Text encoder | Qwen3-VL-4B-Instruct |
| Tasks | Text-to-image, instruction editing, multi-reference (up to 10 images); bounding-box layout in the open model |
| Checkpoints | Base (50 steps) and distilled (16 steps); FP8, INT8, NVFP4 builds |
| Smallest local setup | 8 GB VRAM with the INT8 build |
| Speed claimed by BFL | about 4 s per 1 MP image on RTX 5090, under 9 s on RTX 4070 (distilled) |
| Resolutions on Unicorn | 1K, 2K, 4K |
| Aspect ratios on Unicorn | 1:1, 4:3, 3:4, 3:2, 2:3, 16:9, 9:16, 21:9, 9:21 (edit also auto) |
| Licence | FLUX Kommunity License v1.0 (open weights) |
Where Klein shines
Throughput. Speed is the core of Klein's pitch. Black Forest Labs reports a median API latency of 4.54 seconds for text-to-image and 7.18 seconds for editing at one megapixel, and the distilled checkpoint gets there in 16 steps without guidance. For pipelines that render hundreds of variations, that speed matters more than a few Elo points.
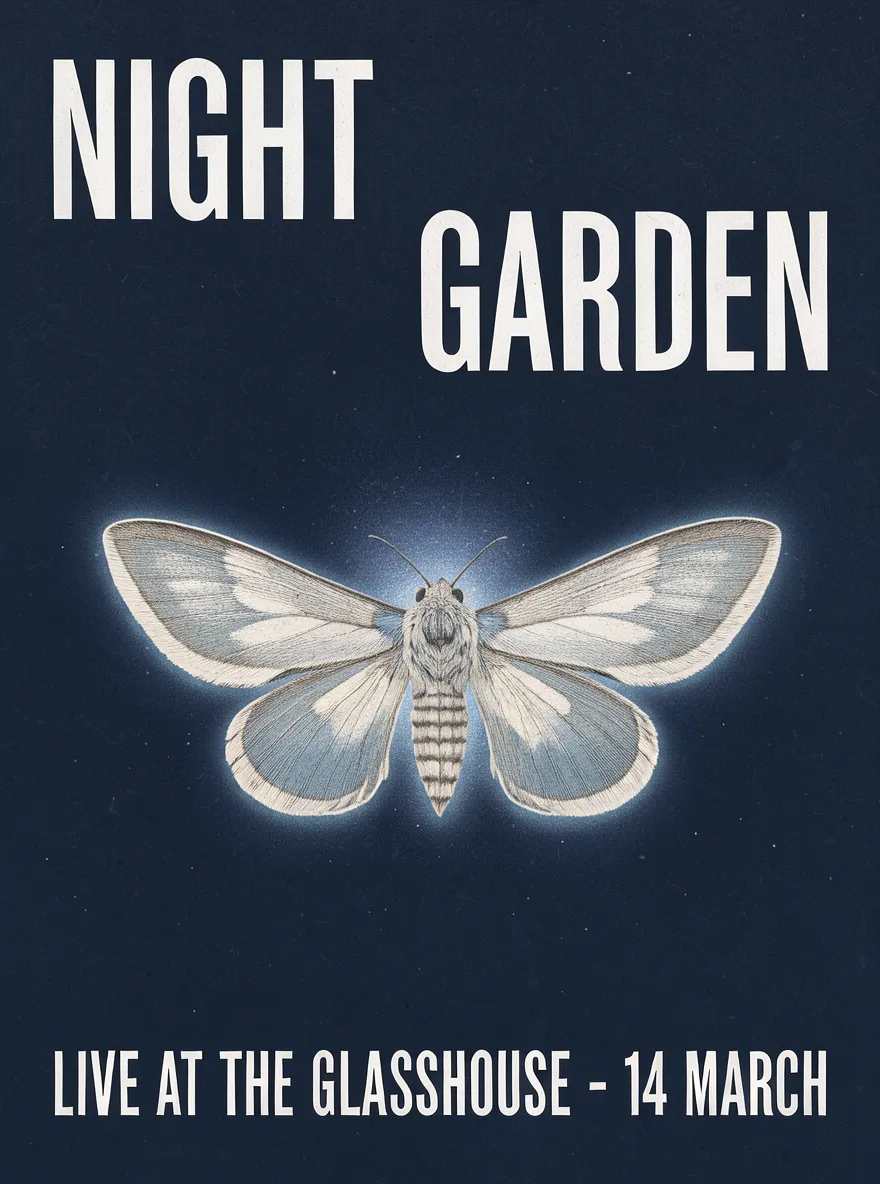
Typography and posters. Early independent tests are encouraging on lettering. One reviewer generated a concert poster with exact strings and found every requested word spelled correctly and placed where asked; another test suite reported that both Klein checkpoints passed every scored text task. For headlines, labels and short slogans, Klein is a credible choice.
Editing and multi-reference work. The edit endpoint takes up to ten images, and testers who used Klein for modification workflows at volume described its editing as solid. Typical jobs: swap a product's colourway, change the season in a street scene, put the same object into several settings, or merge a character sheet and a background into one frame.
Open weights for the right buyer. Teams under the licence's USD 5 million revenue line can prototype on the API and later move the same model in-house, fine-tune LoRAs on the base checkpoint for a house style, and run it on hardware they already own.
Limits and launch-week complaints
Klein's reception has been more mixed than its benchmark charts.
- People and anatomy. The loudest complaint from early users on Reddit and Hacker News concerns human figures: half-melted faces and badly proportioned fingers, often with the stock ComfyUI workflow, and claims that FLUX.2 [klein] 4B handled people better. Some commenters suspect aggressive safety training; others point out that many of these runs skipped the upsampler, and Black Forest Labs has already published updated ComfyUI workflows to fix some launch issues. Test portraits before you commit to Klein for people-heavy work.
- Small text and diagrams. The model card itself warns that rendered text may be inaccurate or distorted, and reviewers noticed garbled lettering on small text in BFL's own showcase. In one structured test, Klein passed every check on only two of six diagrams, writing "12" for "10" on a bar chart and drawing arrows the wrong way in a water-cycle figure.
- Instruction following on hard prompts. The same test scored Klein's distilled model at 75.0% on a four-criterion text-to-image rubric, against 96.9% for GPT Image 2.5 Flare and Nano Banana 2.1. Klein also trailed on counting and spatial relations. The test ran without Klein's prompt expansion and used a small sample, so treat it as a signal rather than a verdict.
- Edits without pixel restoration. A local test without BFL's restoration step found the background drifting outside the edited area. The hosted model adds restoration for exactly this reason, but if you self-host, check edits at full size.
- Licence ceiling. Above USD 5 million in annual revenue, self-hosting commercially needs a separate deal.
Prompting FLUX.3 [klein]
Klein is trained on long, structured captions. Leave enhance_prompt on unless you are writing those captions yourself, and if you turn it off, describe framing, subject, background and lighting explicitly, as BFL's documentation recommends.
For text-to-image, name the medium first, then the subject and its placement, then the light:
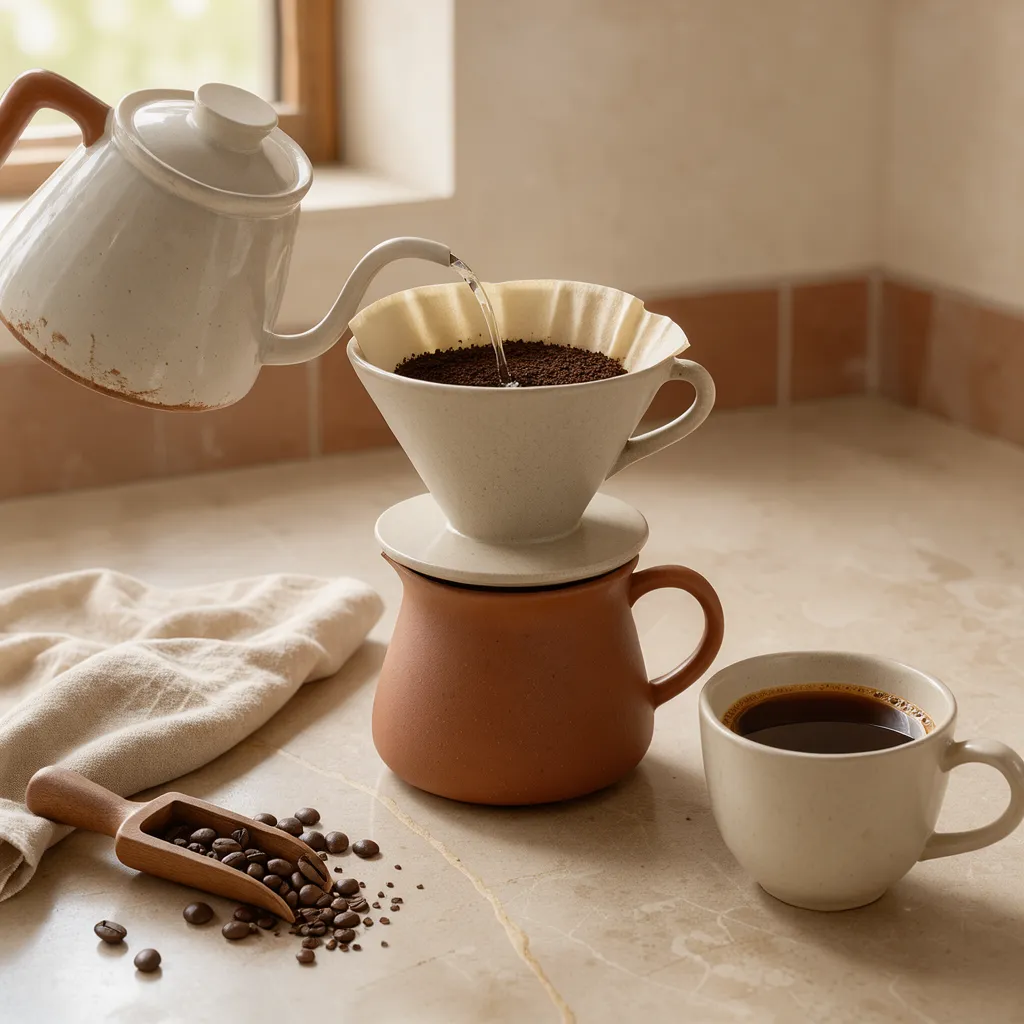
Editorial photograph, three-quarter view of a ceramic pour-over coffee set on a pale travertine counter, morning window light from the left, soft shadows, shallow depth of field, muted cream and terracotta palette.
For typography, put the exact words in quotes and say where they go:
Minimal concert poster, deep navy background, large condensed white headline "NIGHT GARDEN" across the top third, smaller line "LIVE AT THE GLASSHOUSE · 14 MARCH" at the bottom, a single glowing moth illustrated in the centre.
For edits, state the change and what must stay:
Change the jacket to rust-orange corduroy; keep the face, pose, lighting and background unchanged.
For multi-reference jobs, say which image supplies what: "Place the lamp from image 1 on the desk in image 2, matching the warm evening light of image 2."
How it compares with other models on Unicorn
Inside the Black Forest Labs family, FLUX.2 Pro is the heavier, closed option, with up to eight references and 1K or 2K output. By BFL's own charts Klein edges it on preference, and it adds 4K output and ten references. Keep FLUX.2 Pro in the rotation for photoreal people until your own tests say otherwise.
Against the other fast, high-volume models: Z-Image is fully Apache 2.0, a good fit for bulk text-to-image when you need no editing. Seedream 5.0 Flash also offers editing and layer decomposition. Klein stands out among them for ten-image references and its open, fine-tunable weights.
Against the flagships: Nano Banana 2.1 and GPT Image 2.5 Flare followed complex instructions far more reliably in that structured test, and they are the safer bet for counts, diagrams and dense layouts. If a prompt has many constraints, use one of them; if you need a hundred decent variations quickly, Klein is the practical choice.
Getting started
Open Klein text-to-image in the Playground to try prompts and resolutions, or switch to the edit model to upload up to ten reference images. For code, create a key on the API keys page and follow the docs: both models run as jobs on /v1/jobs, with flux-3-klein-text-to-image taking a prompt and flux-3-klein-edit-image taking a prompt plus image_urls. Optional fields are resolution, aspect_ratio, num_images, seed, output_format (png, jpeg or webp) and enhance_prompt.
Verdict
FLUX.3 [klein] packs most of Black Forest Labs' third-generation feature set into a model small enough for a gaming GPU and fast enough to call by the thousand. Its scores over FLUX.2 [klein] are large, its typography is good, and its editing with ten references is a real tool. The weak spots are just as clear: people need testing, hard instructions and diagrams favour the big closed models, and the licence's commercial allowance stops at USD 5 million in annual revenue. As a fast workhorse with an open path to self-hosting, it earns a place in most image pipelines; just keep a flagship model on hand for the jobs it cannot do.
Best for
- High-volume image variations
- Posters and short headlines
- Product and scene edits
- Multi-reference compositions
- Prototyping before self-hosting
Frequently asked questions
Is FLUX.3 [klein] open source?
It is open weights, not open source in the OSI sense. The weights are on Hugging Face under the FLUX Kommunity License v1.0, which allows non-commercial use and commercial use for individuals and companies with under USD 5M in annual revenue.
What resolutions and aspect ratios does FLUX.3 [klein] support on Unicorn API?
Both endpoints output 1K, 2K or 4K images in 1:1, 4:3, 3:4, 3:2, 2:3, 16:9, 9:16, 21:9 and 9:21, and the edit model also accepts auto. Output can be PNG, JPEG or WebP, with up to four images per request.
What changed from FLUX.2 [klein]?
One 5.6B model replaces the 4B and 9B versions, with native 4K, bounding-box layout control, up to ten reference images and a new vision-language text encoder. Black Forest Labs reports gains of 91 Elo in text-to-image and 70 Elo in editing over FLUX.2 [klein] 9B.
Can FLUX.3 [klein] run on my own GPU?
Yes. With the INT8 build it runs on GeForce RTX cards with as little as 8 GB of VRAM. The recommended prompt upsampler needs about 28 GB more, so many local users pair it with a hosted language model instead.
Can FLUX.3 [klein] edit images?
Yes. The edit model takes an instruction plus up to ten reference images, so it can change one photo or combine elements from several into a new scene.
FLUX.3 [klein] vs FLUX.2 Pro: which should I use?
In Black Forest Labs' own tests Klein is preferred over FLUX.2 [pro], and it adds 4K output and ten references. Early users report weaker people shots, so test portraits on both before committing.