Seedream 4.0 API
ByteDance's one model for generating and editing images
ByteDance merged its text-to-image and editing models into one fast system that renders at 4K, combines up to ten references and returns whole image sets, and it went straight to the top of both public image arenas.
- Kind: image
- Made by: ByteDance (ByteDance Seed)
- Price: 5 credits per image (from $0.05; 1 credit = $0.01 on monthly plans, $0.015 as a top-up)
- Released: 2025-09-09
- Open weights: no (Proprietary, API only; no weights published)
- Tasks: Text-to-image, editing, multi-image composition
- Resolution: 1K, 2K or 4K
- Reference images: Up to 10 (edit model)
- Images per run: 1 to 6
- Speed (maker): Under 2 s per 2K image, 10x faster than Seedream 3.0
- Arena placing at launch: #1 text-to-image and image editing (Artificial Analysis)
- Weights: Closed, API only
- Inputs: seed, prompt, image_size, max_images, nsfw_checker, image_resolution
Call it with POST https://api.unicornapi.net/v1/jobs and model bytedance-seedream-v4-text-to-image, or try it in the Playground.
Where it shines
- Generation, editing and multi-reference composition in one model
- Ranked first for both text-to-image and editing at launch
- Native 4K output, trained at up to 4096 × 4096
- Consistent sets of up to six images in one run
- Much better text, formulas and diagrams than Seedream 3.0
Watch out for
- Results vary between runs; generate a few candidates
- Hard multi-step edits can miss parts of the instruction
- Small text and dense copy still need checking
- Closed model with no mask input or fine-tuning
Made with Seedream 4.0 Text to Image
Seedream 4.0 is ByteDance's new image model, announced on 9 September 2025, and its central idea is simple: one model that both creates and edits. Until now ByteDance kept those jobs apart, with Seedream 3.0 for text-to-image and SeedEdit 3.0 for editing. Seedream 4.0 folds them into a single system that takes a prompt alone, a prompt plus one photo to change, or a prompt plus up to ten reference images to combine, and it can return a whole set of related images in one run.
It is also fast and large. ByteDance says inference is more than ten times faster than Seedream 3.0, with a 2K image arriving in under two seconds in ByteDance's own measurements, and the maximum resolution rises from 2K to 4K.
The reason people are paying attention is the leaderboards. Within days of launch, Seedream 4.0 moved to the top of both the Artificial Analysis text-to-image arena and its image-editing arena, passing Google's Nano Banana, released only two weeks earlier. Right now the best-rated image generator and the best-rated image editor are the same model, and it is also one of the fastest.
Where Seedream 4.0 comes from
Seedream is made by ByteDance Seed, the company's foundation-model research team, which also builds the Seedance video models and the models behind the Doubao assistant. In China the model is sold to businesses through Volcano Engine as Doubao-Seedream-4.0. Consumers can use it in the Doubao app and the Jimeng (Dreamina) creative app, and it is also live on ByteDance's Coze agent platform. Internationally it is offered through BytePlus ModelArk and through API providers.
The line has moved quickly. Seedream 3.0 arrived in April 2025 as a bilingual Chinese-English text-to-image model with native 2K output. SeedEdit 3.0 followed in June as its editing partner, built to follow instructions while keeping faces and products intact. Seedream 4.0 is the merger: ByteDance's technical report describes it as extending the SeedEdit 3.0 architecture to multimodal generation and training both tasks together so that each improves the other.
Like every Seedream release, Seedream 4.0 is closed. There are no downloadable weights, no licence for self-hosting and no published parameter count. Access is through ByteDance's apps and APIs, and through providers such as Unicorn.
What changed from Seedream 3.0 and SeedEdit 3.0
One model for every image job. Generation, editing and multi-image composition share one architecture and one endpoint upstream. ByteDance's tests show the unified model beating SeedEdit 3.0 at editing and Seedream 3.0 at generation, with better instruction following, steadier structure, stronger aesthetics and better text.
Speed. ByteDance reports more than ten times faster inference than Seedream 3.0. The technical report puts a 2K image at under two seconds, measured without the language model that rewrites prompts first.
4K output. Maximum resolution doubles from 2K to 4K, with adaptive aspect ratios. Training ran at resolutions from 512 × 512 up to 4096 × 4096 pixels.
Many images in, many images out. You can give the model several references at once, for example a person, an outfit and a location, and ask it to combine them. It can also return a sequence: storyboard panels, comic frames, a product shown from several angles, or a set of matching posters, with the same character and style throughout.
Visual signals. Besides words, the model reads sketches, doodles and marked regions drawn onto an input image, so you can circle where an object should go or sketch a rough layout and have it rendered.
Reasoning and knowledge. ByteDance stresses that the model "thinks" before it draws. It can continue a comic strip, fill in a puzzle, or turn a request into an educational illustration with formulas, tables, charts or chemical structures. The training data added a knowledge-focused set of images from textbooks and papers, plus synthetic formula images generated from LaTeX.
Better text. Text rendering is a clear step up from Seedream 3.0, a point Artificial Analysis singled out in its launch assessment, which puts signs, posters, menus and slides within reach of a single prompt.
How Seedream 4.0 works
The technical report gives a fair amount of detail, though not the size of the model. At its core is an efficient diffusion transformer paired with a powerful variational autoencoder that compresses images into far fewer tokens. Fewer tokens means less compute per image, which is what makes native 2K and 4K generation practical and quick. ByteDance says the design cut training and inference compute by more than ten times compared with Seedream 3.0.
The model was pre-trained on billions of text-image pairs drawn from hundreds of vertical scenarios. For multimodal post-training, a fine-tuned vision-language model reads the input images and the instruction together, which lets one network handle editing and reference work as well as plain generation.
Speed comes from a stack of inference tricks: adversarial distillation and distribution matching to reduce the number of sampling steps, 4-bit and 8-bit quantisation, and speculative decoding.
How it ranks at launch
ByteDance's own MagicBench evaluation puts Seedream 4.0 first across text-to-image and editing, and ahead of GPT-Image-1 on texture, lighting and colour. The more interesting result is how the editors differ. In the report, GPT-Image-1 follows edit instructions most accurately but changes the rest of the picture the most; Gemini 2.5 Flash Image preserves the original best but follows instructions less well; Seedream 4.0 is the most balanced of the three.
Independent blind voting agrees. On launch day Artificial Analysis named Seedream 4.0 the new leader of its text-to-image arena and level with Nano Banana for editing. Two days later it led both arenas, and it still held both first places on 18 September.
There is one caveat in ByteDance's own data. On its DreamEval benchmark, Seedream 4.0 and GPT-4o lead for instruction adherence, but Seedream 4.0 is more variable: its average score is slightly lower while its best-of-four result is higher. Generating a few candidates pays off.
Specs at a glance
| Seedream 4.0 on Unicorn API | |
|---|---|
| Model ids | bytedance-seedream-v4-text-to-image, bytedance-seedream-v4-edit |
| Resolution | image_resolution 1K (default), 2K or 4K |
| Shapes | image_size: square, square_hd (default), portrait 4:3, 3:2, 16:9, landscape 4:3, 3:2, 16:9, 21:9 |
| Reference images (edit) | Up to 10 in image_urls; JPEG, PNG or WebP, up to 30 MB each |
| Images per run | 1 to 6 with max_images |
| Prompt | Up to 5,000 characters |
| Seed | seed, up to 1,000,000 |
| Weights | Closed, API only |
Generating and editing: the two endpoints
On Unicorn the release is split into two models that share the same engine and the same settings.
Seedream 4.0 Text to Image takes a prompt and returns new images. Use it for posters, product shots, portraits, illustrations and image sets.
Seedream 4.0 Edit takes a prompt plus one to ten images in image_urls. With one image it edits: remove a passer-by, relight a scene, swap a jacket's colour, add or replace an object. With several it composes: put the person from the first image in the outfit from the second, in the room from the third. Because the input images are part of the prompt's context, the model also handles style transfer (turn a photo into a watercolour) and follows sketches or marks drawn on the input.
Both models can return a set. Set max_images to the number you want and also say that number in the prompt ("a set of four images..."), since the model decides how many images the request calls for and the setting only caps it.
Where Seedream 4.0 is strong
Edits that change only what you asked for. The balanced editing behaviour in ByteDance's tests matches what early testers found: object insertions land in the marked spot, and outfits transfer from one image to a person in another with only minor slips in fine detail.
Consistent sets. Storyboards, comic panels, product angles and campaign variations keep the same face, costume and palette across images generated in one run.
Text and information graphics. Headlines, signs and short copy come out clean. In one early hands-on test the model wrote out a worked solution to an equation on a blackboard, and ByteDance demonstrates tables, formulas and diagrams.
Photographic polish. ByteDance's evaluation highlights motion, natural light and coherent colour, and photographs and product shots have a finished, commercial look.
High resolution at speed. 4K output and fast generation make the model practical for print, large displays and high-volume work.
Weaknesses and limits
Results vary from run to run. ByteDance's own numbers show a lower average than best-of-four. Expect to generate a few candidates for demanding prompts, or fix a seed once you find a composition you like.
Hard, multi-step edits. The technical report says performance drops on its hardest editing tasks and names multimodal understanding and reasoning as areas to improve. Long chains of instructions in a single edit are where it slips.
Small text is better, not perfect. Testers still found occasional errors in small text and fine details, and rare fonts or dense paragraphs need checking. In a set of seven wallpapers, one early test found the requested dates missing from some images.
Geometry is not always the strongest. In some side-by-side comparisons Nano Banana held 3D structure and on-screen details more precisely.
Closed, with no mask field. There are no weights and no fine-tuning, and the Unicorn API takes no separate mask; you point with words or by drawing on the input image.
How to prompt Seedream 4.0
Write in plain sentences rather than keyword lists: subject, action, setting, then style, light and camera. ByteDance's guidance is that concise, precise prompts work better than stacks of adjectives. Put any text that must appear in double quotes. For edits, use a simple pattern of action, object and result. For multiple references, name each image by position and say what it contributes and what must not change.
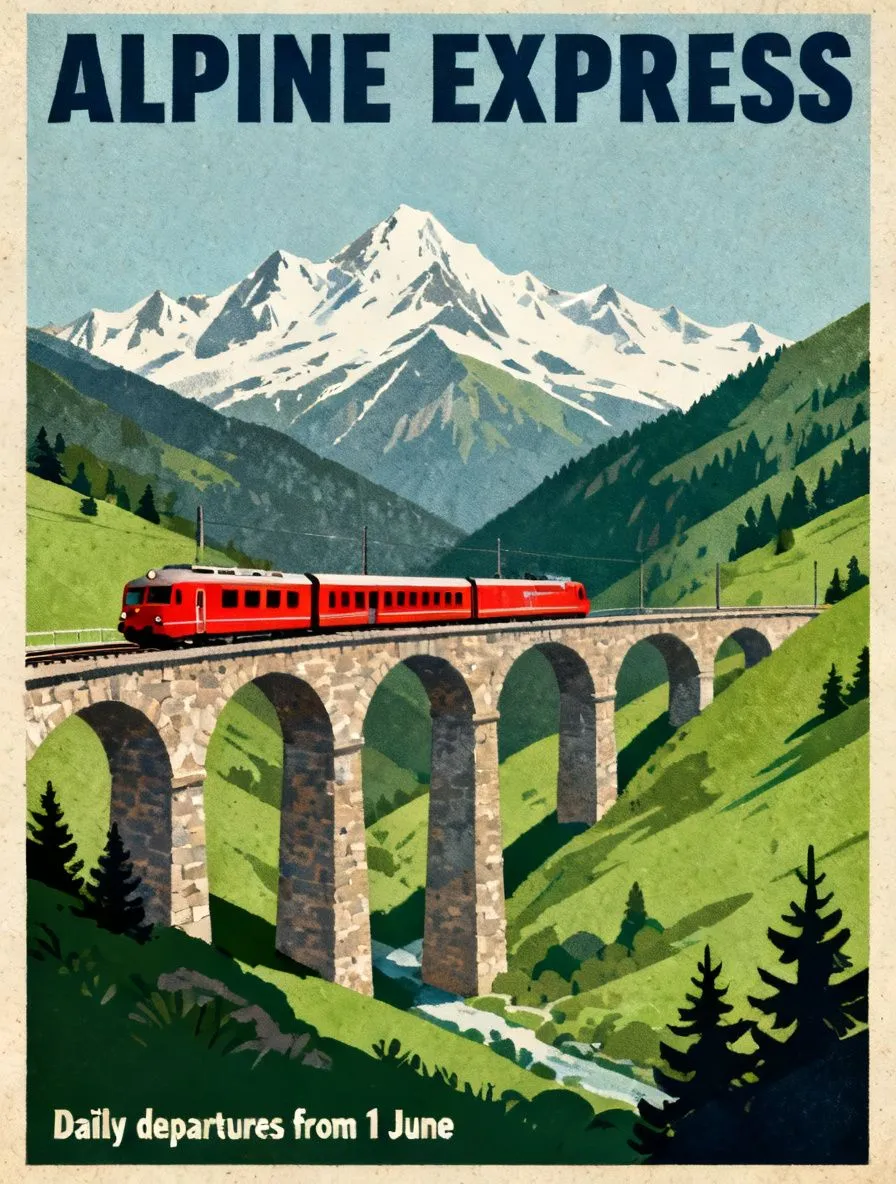
A poster with exact text:
A vintage travel poster for a mountain railway, bold headline "ALPINE EXPRESS" at the top, a red train crossing a stone viaduct above a green valley, small text at the bottom "Daily departures from 1 June", flat screen-print colours
A focused edit:
Change the car in image 1 to a deep green convertible, keep the street, the people and the lighting exactly the same
Several references combined:
The man from image 1 wearing the jacket from image 2, sitting at the café table from image 3, morning light, keep his face and hairstyle unchanged
A consistent set:
A set of four images showing the same small orange robot exploring a library: reaching for a book, reading by a lamp, climbing a ladder, asleep on an open atlas. Same robot and same warm palette in every image
Set image_size explicitly, since the default is square. Explore at 1K, then rerun the keeper at 2K or 4K with the same seed.
Seedream 4.0 versus other models in the catalog
- Nano Banana is Google's Gemini 2.5 Flash Image, launched two weeks earlier, and the model Seedream 4.0 overtook in both arenas. Nano Banana preserves the original image very well and, in some side-by-side tests, holds 3D structure and small on-screen details more precisely; Seedream 4.0 follows instructions more readily, renders up to 4K and returns consistent sets in one call.
- Imagen 4, in Fast, standard and Ultra versions, is Google's text-to-image family. It has no editing mode on Unicorn; Seedream 4.0 covers generation and editing with one engine.
- Ideogram V3 is a typography-focused generator with separate edit and remix models. It suits design work centred on lettering; Seedream 4.0 adds multi-reference composition, sets and 4K.
- Qwen Image Edit is Alibaba's open-weight editor. Pick it if open weights matter; pick Seedream 4.0 for its arena-leading quality, 4K output and multi-image input.
Choosing a resolution and a workflow
The image_resolution setting is the main lever. 1K is the default and the quickest way to test a prompt, a composition or a set of references. 2K suits most web and social work, and it is the size ByteDance used for its under-two-seconds speed figure. 4K is there for print, large displays and catalogue images that will be cropped later, and the model was trained on images up to 4096 × 4096 pixels, so it is a native size rather than an upscale.
A practical loop: explore at 1K with a handful of candidates, since the model's results vary from run to run, then lock the seed of the one you like and rerun it at 4K for the final file. For sets, keep max_images and the number in the prompt in step, and describe what must stay constant (the face, the costume, the palette) as clearly as what should change between images.
Getting started
Open the Seedream 4.0 playground to try prompts in the browser, or the edit playground to upload images and describe changes. For code, create a key on the API keys page and read the docs: send a job to /v1/jobs with the model id, a prompt, optional image_size, image_resolution and max_images, and for the edit model an image_urls array, then poll for the result. The API tab on this page has complete examples.
Verdict
Seedream 4.0 is the release where ByteDance's image work comes together. Generation, editing and multi-reference composition now live in one fast model with 4K output, and independent voters rank it first for both creating and editing images. It is not flawless: results vary between runs, the hardest multi-step edits trip it up, and small text still needs a check. But for anyone who wants one fast model to make, change and combine images at production resolution, Seedream 4.0 sets the pace.
Best for
- Instruction-based photo edits
- Combining people, products and places from references
- Storyboards, comics and consistent image sets
- Posters and signs with short text
- Product and marketing imagery at 4K
Frequently asked questions
Is Seedream 4.0 open source?
No. ByteDance offers Seedream 4.0 only through its own apps and APIs and through API providers such as Unicorn. No weights, self-hosting licence or parameter count have been published.
How fast is Seedream 4.0?
ByteDance reports more than ten times faster inference than Seedream 3.0, with a 2K image in under two seconds in its own measurements, taken without the prompt-rewriting language model.
Can Seedream 4.0 edit images?
Yes. The Seedream 4.0 Edit model takes a prompt and one to ten images in image_urls. With one image it makes the change you describe; with several it combines them, for example a person, an outfit and a location.
Seedream 4.0 vs Nano Banana: which is better?
At launch Seedream 4.0 overtook Nano Banana on both the Artificial Analysis text-to-image and image-editing arenas. Nano Banana preserves the original image very well; Seedream 4.0 follows instructions more readily, renders up to 4K and returns consistent image sets.
Can Seedream 4.0 generate 4K images?
Yes. Set image_resolution to 4K. The model was trained at resolutions up to 4096 × 4096 pixels, so 4K is a native output size rather than an upscale.
How do I get several consistent images from Seedream 4.0?
Set max_images to the number you want, up to six, and state the same number in the prompt, for example a set of four storyboard panels with the same character.